

Cross-cloud Lakehouse and Egress-Caching: What Google Cloud Next 2026 Changes for DACH Architects
Google Cloud Next 2026 turns cross-cloud into a cost issue: How Lakehouse architecture and egress caching break vendor lock-in and data silos.
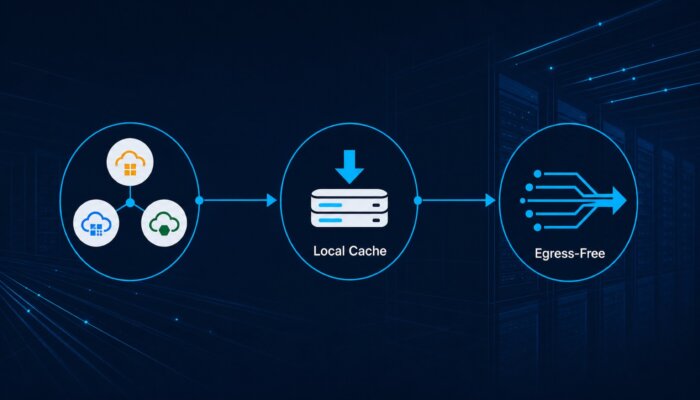
At Cloud Next 2026, Google announced building blocks that take multi-cloud from architectural theory to an operational decision. DACH CIOs who still believe cross-cloud strategy fails on egress costs and data silos should look closely: today the lever lies in where the data resides and what moving it costs.
The Essentials at a Glance
- Cross-cloud Lakehouse (formerly BigLake) now enables queries across AWS, Azure and GCP data sources without full replication, and the cross-cloud caching layer keeps the first read in the home system, confining egress fees to recurring queries.
- Gemini Enterprise Agent Platform combines agent registries, skill registries and governance in one layer that is explicitly built for multi-cloud deployments and serves as the control plane over existing workloads.
- Agentic Data Cloud turns data storage into a strategic question: whoever controls the master tables controls the agent stack that uses them.
- AWS and Google have separately announced a multi-cloud deployment cooperation, which makes workloads technically easier to port between the hyperscalers while further intensifying the race for the data layer.
- Operational consequence for CIOs: The question has shifted from “which cloud” to “where does the master data stay, where may computations run, who carries the caching risk”.
Egress as a Hidden Tax on Every Multi-Cloud Idea
Anyone who has seriously tried to spread workloads across two hyperscalers over the past three years knows the reflex from the CFO side: egress costs. AWS, Azure and GCP charge per gigabyte of outgoing traffic amounts that quickly reach five figures per month for an 80-terabyte pipeline. These rates are no accident, they are what vendor lock-in looks like as a balance sheet line item. Data that once sits in a bucket comes back out at a price.
The cross-cloud caching feature that Google presented at Next 2026 addresses exactly this point. It stores data that has been pulled across the cloud boundary once in a local lakehouse cache, so recurring queries no longer trigger egress every single time. For a reporting setup that consumes the same dataset from an S3 bucket every day, this ideally means one order of magnitude less outgoing traffic. The architectural truth behind it: caching is nothing new, yet when a hyperscaler offers it as a native service across foreign cloud boundaries, that massively shifts the ROI calculation for cross-cloud.
A DACH Example Makes the Order of Magnitude Tangible
A mid-sized industrial group that collects its machine data in AWS S3 and analyzes it via GCP BigQuery reports around 12 TB of cross-cloud egress per month. At current AWS rates, that adds up to almost 1,080 euros per month for data movement alone. With a cache hit rate of 70 percent on the recurring analytics queries, outgoing traffic drops to roughly 3.6 TB and the bill to around 330 euros. Over a year, that is a difference of 9,000 euros on a single data path. Anyone running several pipelines of this kind quickly talks about effects in the six figures.
From Data Silo to Borderless Lakehouse
The second shift comes from the lakehouse itself. Google calls the new variant “borderless”, the lakehouse layer can reference tables that physically reside in S3 or Azure Data Lake without the data having to be replicated into BigQuery. For engineering teams this means: less ETL, fewer sync jobs, fewer places where a schema drift breaks the report. For CIOs this means: the question of where data “belongs” can be answered anew politically and contractually without every answer immediately triggering a migration project.
The flip side: whoever controls the lakehouse layer controls the query logic. Google positions itself here as a neutral broker, which is strategically clever, its own compute becomes the standard query engine over foreign buckets. AWS and Azure have comparable initiatives, yet each is more firmly anchored in its own ecosystem. The choice of which lakehouse layer becomes the de facto standard in a DACH enterprise is therefore a vendor-strategic decision with a long half-life.
“Multi-cloud has so far been a compliance answer. With the new lakehouse and caching layers it becomes an architectural option, yet the choice of who leads the data layer remains a long-term lock-in decision.”
Agent Stack: Whoever Controls the Data Controls the Skills
The Gemini Enterprise Agent Platform and the Agentic Data Cloud are the more strategic announcement. Google combines agent registry, skill registry, tool registry and governance in a layer that is explicitly designed to steer AWS, Azure and GCP workloads together. With this, Google’s pitch is “we become the control plane over your existing apps”, with the apps staying exactly where they run. From a CIO perspective that is attractive because it changes the investment equation: the budget flows into an abstracted control subscription, and the workload migration project drops off the plan.
However, this only shifts the risk one layer up. Anyone who discovers in two years that the agent registry and the tool inventory sit with Google will experience the same lock-in effect with a “control plane swap” that multi-cloud was actually meant to avoid. The only sustainable answer: enforce open standards for agent definitions, skill schemas and tool manifests before proprietary formats create facts on the ground.
Compliance Lands on the Cross-Cloud Layer
What often gets lost in the architecture debate: GDPR, NIS2 and the EU AI Act leave the choice of cloud provider open, and they do prescribe where data is processed and who may see it. A cross-cloud caching layer that holds personal data in a GCP cache while the master table sits in a German AWS data center is a delicate matter under data protection law. The operational question is: which data category may be cached where? And how is the cache lifecycle documented when the supervisory authority comes asking?
The vendor answer will be “policy-driven caching”, in other words rules that define which data classes may cross which cloud boundaries. In practice this means: a data classification schema must be in place before the first productive cross-cloud pipeline is built. Anyone who postpones this builds themselves an audit finding generator.
Three Check Questions Before the Next Multi-Cloud Step
1. Where does the master data reside and where may copies of it reside? Caching is a compliance question disguised as a performance question. No data classification, no cross-cloud cache.
2. Which query engine becomes the standard? Lakehouse layers have half-lives of five to ten years. The choice of whether BigQuery, Athena, Synapse or Snowflake becomes the dominant query path is a vendor-strategic decision that goes well beyond tooling.
3. Who controls the agent control plane? If the agent registry and the tool inventory sit with one hyperscaler, multi-cloud works well at the compute layer while the intelligence layer becomes recentralized. The open standard discussions need to happen now, while the outcome is still open.
Frequently Asked Questions
What does cross-cloud caching actually cost?
Google did not name separate list prices at the launch. The economic logic lies in reducing existing egress fees, and the cache itself is billed via BigQuery slot reservations or on-demand pricing, meaning through the compute layer, with no separate caching tariff of its own.
Does this only work with Google at the center?
Currently yes, the cross-cloud lakehouse implementation requires BigQuery as the query engine. AWS and Azure have comparable approaches (Athena Federated Queries, Synapse Link) that each put their home engine at the center. Genuine vendor neutrality exists only through open standards such as Apache Iceberg, which all three hyperscalers now support.
Is this relevant for the DACH Mittelstand or purely a corporate topic?
It becomes relevant from the point at which a company runs two productive cloud accounts in parallel, which is more common in the DACH Mittelstand than assumed, often through acquisitions or through SaaS providers with hard-wired cloud backends. Anyone paying more than 500 euros in egress per month should run the ROI calculation.
What should be clarified before the first cross-cloud pipeline project?
Three things: a data classification schema with clear caching permissions per category, a decision on which query engine becomes the standard language and a documented escalation path for audit findings around cache contents. Without these three points, the first letter from the authorities will hurt.
How does egress caching differ from a classic CDN?
A CDN accelerates delivered content at the edge of the network. Egress caching kicks in earlier: it keeps frequently queried datasets close to the compute region so that repeated cross-cloud queries avoid triggering expensive egress fees every time. The gain lies in the cost curve.
Image source: AI-generated (June 2026), C2PA certificate embedded in the image
Translated from the German original using artificial intelligence. The German version is authoritative.
More from the MBF Media Network
- MyBusinessFuture: The strategic view on AI governance in the Mittelstand
- SecurityToday: What cloud workload shifting means for CISOs
- Digital Chiefs: Vendor lock-in as a board topic for 2026


